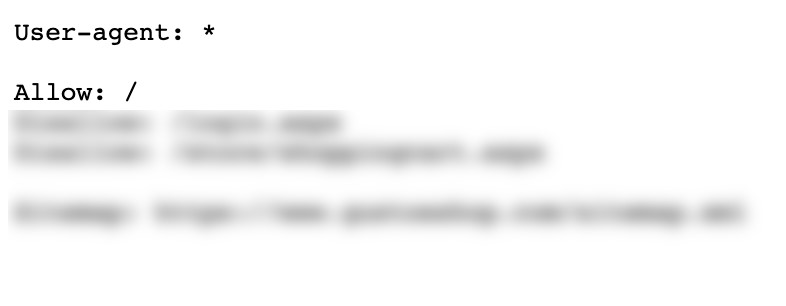
The Allow directive in a robots.txt file tells crawlers which pages or folders they're permitted to access, even inside a section that's otherwise blocked. A typical robots.txt disallows an entire directory, then adds an Allow line for one specific file or subfolder inside it that should still be crawled. A site might block /private/, for instance, but allow /private/press-kit/ so that one page stays reachable.
Search engines apply the most specific matching rule when directives conflict, so a longer, more precise Allow path overrides a shorter Disallow path covering the same area. Allow isn't required for pages that aren't blocked elsewhere, since crawling is open by default; the directive only matters where it's carving out an exception to a broader block. An Allow rule that's less specific than the Disallow around it is a common way pages end up unexpectedly excluded from crawling, which is worth checking whenever a page that should be indexable isn't showing up.