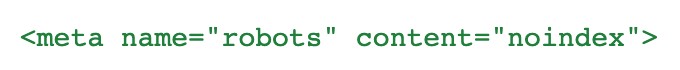
A noindex tag, either a <meta name="robots" content="noindex"> line in a page's head or an X-Robots-Tag HTTP header for non-HTML files, tells search engines directly not to include a page in their index. Unlike a robots.txt disallow, which only blocks crawling, noindex requires the page to actually be crawled so the crawler can see and honor the tag.
Common uses include internal search results pages, thank-you or confirmation pages that shouldn't show up for anyone searching organically, staging or duplicate content, and thin utility pages that exist for functionality rather than to rank. It's a directive search engines respect reliably, unlike robots.txt exclusions, which is why noindex is the correct tool specifically for "keep this page out of search results," while robots.txt remains the tool for "don't spend crawl budget here." Mixing the two up, disallowing a page in robots.txt while also expecting noindex to remove it, actually backfires: if the crawler can't access the page, it never sees the noindex tag telling it to drop the page from the index.